Original paper
The Llama 3 Herd of Models
- Publication
- Publication venue not yet verified
- First submitted to arXiv
- arXiv:2407.21783
Cite this paper · BibTeX
The citation identifies the linked source version. It cites the original paper and its authors.
@misc{transformersllama32024,
  title = {{The Llama 3 Herd of Models}},
  author = {Aaron Grattafiori and Abhimanyu Dubey and Abhinav Jauhri and Abhinav Pandey and Abhishek Kadian and Ahmad Al-Dahle and Aiesha Letman and Akhil Mathur and Alan Schelten and Alex Vaughan and Amy Yang and Angela Fan and Anirudh Goyal and Anthony Hartshorn and Aobo Yang and Archi Mitra and Archie Sravankumar and Artem Korenev and Arthur Hinsvark and Arun Rao and Aston Zhang and Aurelien Rodriguez and Austen Gregerson and Ava Spataru and Baptiste Roziere and Bethany Biron and Binh Tang and Bobbie Chern and Charlotte Caucheteux and Chaya Nayak and Chloe Bi and Chris Marra and Chris McConnell and Christian Keller and Christophe Touret and Chunyang Wu and Corinne Wong and Cristian Canton Ferrer and Cyrus Nikolaidis and Damien Allonsius and Daniel Song and Danielle Pintz and Danny Livshits and Danny Wyatt and David Esiobu and Dhruv Choudhary and Dhruv Mahajan and Diego Garcia-Olano and Diego Perino and Dieuwke Hupkes and Egor Lakomkin and Ehab AlBadawy and Elina Lobanova and Emily Dinan and Eric Michael Smith and Filip Radenovic and Francisco Guzmán and Frank Zhang and Gabriel Synnaeve and Gabrielle Lee and Georgia Lewis Anderson and Govind Thattai and Graeme Nail and Gregoire Mialon and Guan Pang and Guillem Cucurell and Hailey Nguyen and Hannah Korevaar and Hu Xu and Hugo Touvron and Iliyan Zarov and Imanol Arrieta Ibarra and Isabel Kloumann and Ishan Misra and Ivan Evtimov and Jack Zhang and Jade Copet and Jaewon Lee and Jan Geffert and Jana Vranes and Jason Park and Jay Mahadeokar and Jeet Shah and Jelmer van der Linde and Jennifer Billock and Jenny Hong and Jenya Lee and Jeremy Fu and Jianfeng Chi and Jianyu Huang and Jiawen Liu and Jie Wang and Jiecao Yu and Joanna Bitton and Joe Spisak and Jongsoo Park and Joseph Rocca and Joshua Johnstun and Joshua Saxe and Junteng Jia and Kalyan Vasuden Alwala and Karthik Prasad and Kartikeya Upasani and Kate Plawiak and Ke Li and Kenneth Heafield and Kevin Stone and Khalid El-Arini and Krithika Iyer and Kshitiz Malik and Kuenley Chiu and Kunal Bhalla and Kushal Lakhotia and Lauren Rantala-Yeary and Laurens van der Maaten and Lawrence Chen and Liang Tan and Liz Jenkins and Louis Martin and Lovish Madaan and Lubo Malo and Lukas Blecher and Lukas Landzaat and Luke de Oliveira and Madeline Muzzi and Mahesh Pasupuleti and Mannat Singh and Manohar Paluri and Marcin Kardas and Maria Tsimpoukelli and Mathew Oldham and Mathieu Rita and Maya Pavlova and Melanie Kambadur and Mike Lewis and Min Si and Mitesh Kumar Singh and Mona Hassan and Naman Goyal and Narjes Torabi and Nikolay Bashlykov and Nikolay Bogoychev and Niladri Chatterji and Ning Zhang and Olivier Duchenne and Onur Çelebi and Patrick Alrassy and Pengchuan Zhang and Pengwei Li and Petar Vasic and Peter Weng and Prajjwal Bhargava and Pratik Dubal and Praveen Krishnan and Punit Singh Koura and Puxin Xu and Qing He and Qingxiao Dong and Ragavan Srinivasan and Raj Ganapathy and Ramon Calderer and Ricardo Silveira Cabral and Robert Stojnic and Roberta Raileanu and Rohan Maheswari and Rohit Girdhar and Rohit Patel and Romain Sauvestre and Ronnie Polidoro and Roshan Sumbaly and Ross Taylor and Ruan Silva and Rui Hou and Rui Wang and Saghar Hosseini and Sahana Chennabasappa and Sanjay Singh and Sean Bell and Seohyun Sonia Kim and Sergey Edunov and Shaoliang Nie and Sharan Narang and Sharath Raparthy and Sheng Shen and Shengye Wan and Shruti Bhosale and Shun Zhang and Simon Vandenhende and Soumya Batra and Spencer Whitman and Sten Sootla and Stephane Collot and Suchin Gururangan and Sydney Borodinsky and Tamar Herman and Tara Fowler and Tarek Sheasha and Thomas Georgiou and Thomas Scialom and Tobias Speckbacher and Todor Mihaylov and Tong Xiao and Ujjwal Karn and Vedanuj Goswami and Vibhor Gupta and Vignesh Ramanathan and Viktor Kerkez and Vincent Gonguet and Virginie Do and Vish Vogeti and Vítor Albiero and Vladan Petrovic and Weiwei Chu and Wenhan Xiong and Wenyin Fu and Whitney Meers and Xavier Martinet and Xiaodong Wang and Xiaofang Wang and Xiaoqing Ellen Tan and Xide Xia and Xinfeng Xie and Xuchao Jia and Xuewei Wang and Yaelle Goldschlag and Yashesh Gaur and Yasmine Babaei and Yi Wen and Yiwen Song and Yuchen Zhang and Yue Li and Yuning Mao and Zacharie Delpierre Coudert and Zheng Yan and Zhengxing Chen and Zoe Papakipos and Aaditya Singh and Aayushi Srivastava and Abha Jain and Adam Kelsey and Adam Shajnfeld and Adithya Gangidi and Adolfo Victoria and Ahuva Goldstand and Ajay Menon and Ajay Sharma and Alex Boesenberg and Alexei Baevski and Allie Feinstein and Amanda Kallet and Amit Sangani and Amos Teo and Anam Yunus and Andrei Lupu and Andres Alvarado and Andrew Caples and Andrew Gu and Andrew Ho and Andrew Poulton and Andrew Ryan and Ankit Ramchandani and Annie Dong and Annie Franco and Anuj Goyal and Aparajita Saraf and Arkabandhu Chowdhury and Ashley Gabriel and Ashwin Bharambe and Assaf Eisenman and Azadeh Yazdan and Beau James and Ben Maurer and Benjamin Leonhardi and Bernie Huang and Beth Loyd and Beto De Paola and Bhargavi Paranjape and Bing Liu and Bo Wu and Boyu Ni and Braden Hancock and Bram Wasti and Brandon Spence and Brani Stojkovic and Brian Gamido and Britt Montalvo and Carl Parker and Carly Burton and Catalina Mejia and Ce Liu and Changhan Wang and Changkyu Kim and Chao Zhou and Chester Hu and Ching-Hsiang Chu and Chris Cai and Chris Tindal and Christoph Feichtenhofer and Cynthia Gao and Damon Civin and Dana Beaty and Daniel Kreymer and Daniel Li and David Adkins and David Xu and Davide Testuggine and Delia David and Devi Parikh and Diana Liskovich and Didem Foss and Dingkang Wang and Duc Le and Dustin Holland and Edward Dowling and Eissa Jamil and Elaine Montgomery and Eleonora Presani and Emily Hahn and Emily Wood and Eric-Tuan Le and Erik Brinkman and Esteban Arcaute and Evan Dunbar and Evan Smothers and Fei Sun and Felix Kreuk and Feng Tian and Filippos Kokkinos and Firat Ozgenel and Francesco Caggioni and Frank Kanayet and Frank Seide and Gabriela Medina Florez and Gabriella Schwarz and Gada Badeer and Georgia Swee and Gil Halpern and Grant Herman and Grigory Sizov and Guangyi and Zhang and Guna Lakshminarayanan and Hakan Inan and Hamid Shojanazeri and Han Zou and Hannah Wang and Hanwen Zha and Haroun Habeeb and Harrison Rudolph and Helen Suk and Henry Aspegren and Hunter Goldman and Hongyuan Zhan and Ibrahim Damlaj and Igor Molybog and Igor Tufanov and Ilias Leontiadis and Irina-Elena Veliche and Itai Gat and Jake Weissman and James Geboski and James Kohli and Janice Lam and Japhet Asher and Jean-Baptiste Gaya and Jeff Marcus and Jeff Tang and Jennifer Chan and Jenny Zhen and Jeremy Reizenstein and Jeremy Teboul and Jessica Zhong and Jian Jin and Jingyi Yang and Joe Cummings and Jon Carvill and Jon Shepard and Jonathan McPhie and Jonathan Torres and Josh Ginsburg and Junjie Wang and Kai Wu and Kam Hou U and Karan Saxena and Kartikay Khandelwal and Katayoun Zand and Kathy Matosich and Kaushik Veeraraghavan and Kelly Michelena and Keqian Li and Kiran Jagadeesh and Kun Huang and Kunal Chawla and Kyle Huang and Lailin Chen and Lakshya Garg and Lavender A and Leandro Silva and Lee Bell and Lei Zhang and Liangpeng Guo and Licheng Yu and Liron Moshkovich and Luca Wehrstedt and Madian Khabsa and Manav Avalani and Manish Bhatt and Martynas Mankus and Matan Hasson and Matthew Lennie and Matthias Reso and Maxim Groshev and Maxim Naumov and Maya Lathi and Meghan Keneally and Miao Liu and Michael L. Seltzer and Michal Valko and Michelle Restrepo and Mihir Patel and Mik Vyatskov and Mikayel Samvelyan and Mike Clark and Mike Macey and Mike Wang and Miquel Jubert Hermoso and Mo Metanat and Mohammad Rastegari and Munish Bansal and Nandhini Santhanam and Natascha Parks and Natasha White and Navyata Bawa and Nayan Singhal and Nick Egebo and Nicolas Usunier and Nikhil Mehta and Nikolay Pavlovich Laptev and Ning Dong and Norman Cheng and Oleg Chernoguz and Olivia Hart and Omkar Salpekar and Ozlem Kalinli and Parkin Kent and Parth Parekh and Paul Saab and Pavan Balaji and Pedro Rittner and Philip Bontrager and Pierre Roux and Piotr Dollar and Polina Zvyagina and Prashant Ratanchandani and Pritish Yuvraj and Qian Liang and Rachad Alao and Rachel Rodriguez and Rafi Ayub and Raghotham Murthy and Raghu Nayani and Rahul Mitra and Rangaprabhu Parthasarathy and Raymond Li and Rebekkah Hogan and Robin Battey and Rocky Wang and Russ Howes and Ruty Rinott and Sachin Mehta and Sachin Siby and Sai Jayesh Bondu and Samyak Datta and Sara Chugh and Sara Hunt and Sargun Dhillon and Sasha Sidorov and Satadru Pan and Saurabh Mahajan and Saurabh Verma and Seiji Yamamoto and Sharadh Ramaswamy and Shaun Lindsay and Shaun Lindsay and Sheng Feng and Shenghao Lin and Shengxin Cindy Zha and Shishir Patil and Shiva Shankar and Shuqiang Zhang and Shuqiang Zhang and Sinong Wang and Sneha Agarwal and Soji Sajuyigbe and Soumith Chintala and Stephanie Max and Stephen Chen and Steve Kehoe and Steve Satterfield and Sudarshan Govindaprasad and Sumit Gupta and Summer Deng and Sungmin Cho and Sunny Virk and Suraj Subramanian and Sy Choudhury and Sydney Goldman and Tal Remez and Tamar Glaser and Tamara Best and Thilo Koehler and Thomas Robinson and Tianhe Li and Tianjun Zhang and Tim Matthews and Timothy Chou and Tzook Shaked and Varun Vontimitta and Victoria Ajayi and Victoria Montanez and Vijai Mohan and Vinay Satish Kumar and Vishal Mangla and Vlad Ionescu and Vlad Poenaru and Vlad Tiberiu Mihailescu and Vladimir Ivanov and Wei Li and Wenchen Wang and Wenwen Jiang and Wes Bouaziz and Will Constable and Xiaocheng Tang and Xiaojian Wu and Xiaolan Wang and Xilun Wu and Xinbo Gao and Yaniv Kleinman and Yanjun Chen and Ye Hu and Ye Jia and Ye Qi and Yenda Li and Yilin Zhang and Ying Zhang and Yossi Adi and Youngjin Nam and Yu and Wang and Yu Zhao and Yuchen Hao and Yundi Qian and Yunlu Li and Yuzi He and Zach Rait and Zachary DeVito and Zef Rosnbrick and Zhaoduo Wen and Zhenyu Yang and Zhiwei Zhao and Zhiyu Ma},
  year = {2024},
  eprint = {2407.21783},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2407.21783}
}
In July 2024, Meta released the weights of the Llama 3.1 series. The largest model has 405 billion parameters.
Before that, every model that could be compared head-to-head with GPT-4 was available only through an API. For the first time, a model that tied GPT-4 on most benchmarks had weights you could simply download.
Released alongside the weights was a technical report of more than ninety pages. Its title calls the models a "herd," and it covers three sizes, 8B, 70B, and 405B. It goes through data cleaning, scaling laws, training infrastructure, post-training, and inference, and ends with experiments extending the models to images, video, and speech.
A report this long is easy to read as a checklist. This note takes a different route and follows one principle the report itself emphasizes: keep the development process simple. For the sake of this principle, Meta passed over some more fashionable options, and at several key points used a very plain technique, averaging several models together.
Defining the problem
The authors see three levers for developing high-quality foundation models: data, scale, and managing complexity.
The first two are intuitive. On data, Llama 3 was pretrained on about 15T multilingual tokens, against only 1.8T for Llama 2. On scale, the 405B flagship used FLOPs, roughly 50 times the largest Llama 2 model.
The third lever deserves a closer look. For the architecture, the authors chose a standard dense Transformer rather than a mixture of experts (MoE). For post-training, they chose a combination of supervised fine-tuning (SFT), rejection sampling, and DPO rather than reinforcement learning such as PPO. Both choices come down to the same thing, training that stays stable and scales up easily.
Let's sanity-check the scale first. The compute for training a dense Transformer is commonly estimated as , where is the parameter count and the number of training tokens:
This matches the report's . If all 16,384 H100s ran the whole time, each actually reaching 400 TFLOPs, pure compute time would be about seconds, or roughly 67 days. This is only a rough estimate; early training used fewer GPUs, and there were all sorts of interruptions.
When a job has to run stably and without a break on more than ten thousand GPUs for over two months, every choice that adds "a little more complexity" can turn into another training interruption. That is the backdrop for the whole report.
Solving the problem
Data: more effort on cleaning than on volume
The pretraining data has a knowledge cutoff at the end of 2023 and comes mostly from the web. The cleaning pipeline includes the following steps:
- A custom HTML parser. Math and code content keeps its structure. Math is often rendered as images, with the formula written in the alt attribute, so alt text is kept as well. The authors also found that Markdown markup actually hurts models trained mainly on web data, so they removed all of it.
- Three levels of deduplication. At the URL level, the latest version is kept. At the document level, MinHash removes near-duplicates. The line level is aggressive: every line that appears more than 6 times within each bucket of 30 million documents is deleted. The authors admit this also removed some high-quality common text, but it clearly helped in evaluations.
- Model-based quality filtering. fastText judges whether a piece of text "would be referenced by Wikipedia," and DistilRoberta, trained on data labeled by Llama 2, assigns quality scores. Code and math have their own dedicated classifiers and extraction pipelines. Multilingual data is first split into 176 languages by language identification, then deduplicated and filtered per language.
The final data mix is roughly 50% general knowledge, 25% math and reasoning, 17% code, and 8% multilingual.
The mix was chosen through scaling-law experiments, trying different mixes on small models first and then predicting how large models would perform. For small domain-specific datasets, the authors evaluate their value with a cheaper method. Take an 8B model halfway through training and linearly anneal its learning rate to 0 over 40B tokens, with the new dataset making up 30% of the annealing data, then look at how the scores change. This is far cheaper than running a scaling-law experiment for every small dataset.
Scale: scaling laws should predict benchmark scores
Standard scaling laws predict next-token loss, but what people really care about is benchmark scores. The authors take two steps:
- First fit the relationship between compute and the negative log-likelihood (NLL) of the correct answer on downstream tasks, using small models from 40M to 16B parameters with compute between and FLOPs.
- Then fit an S-shaped relationship between NLL and accuracy. This step adds the Llama 2 family, since those models used far more compute than the small models.
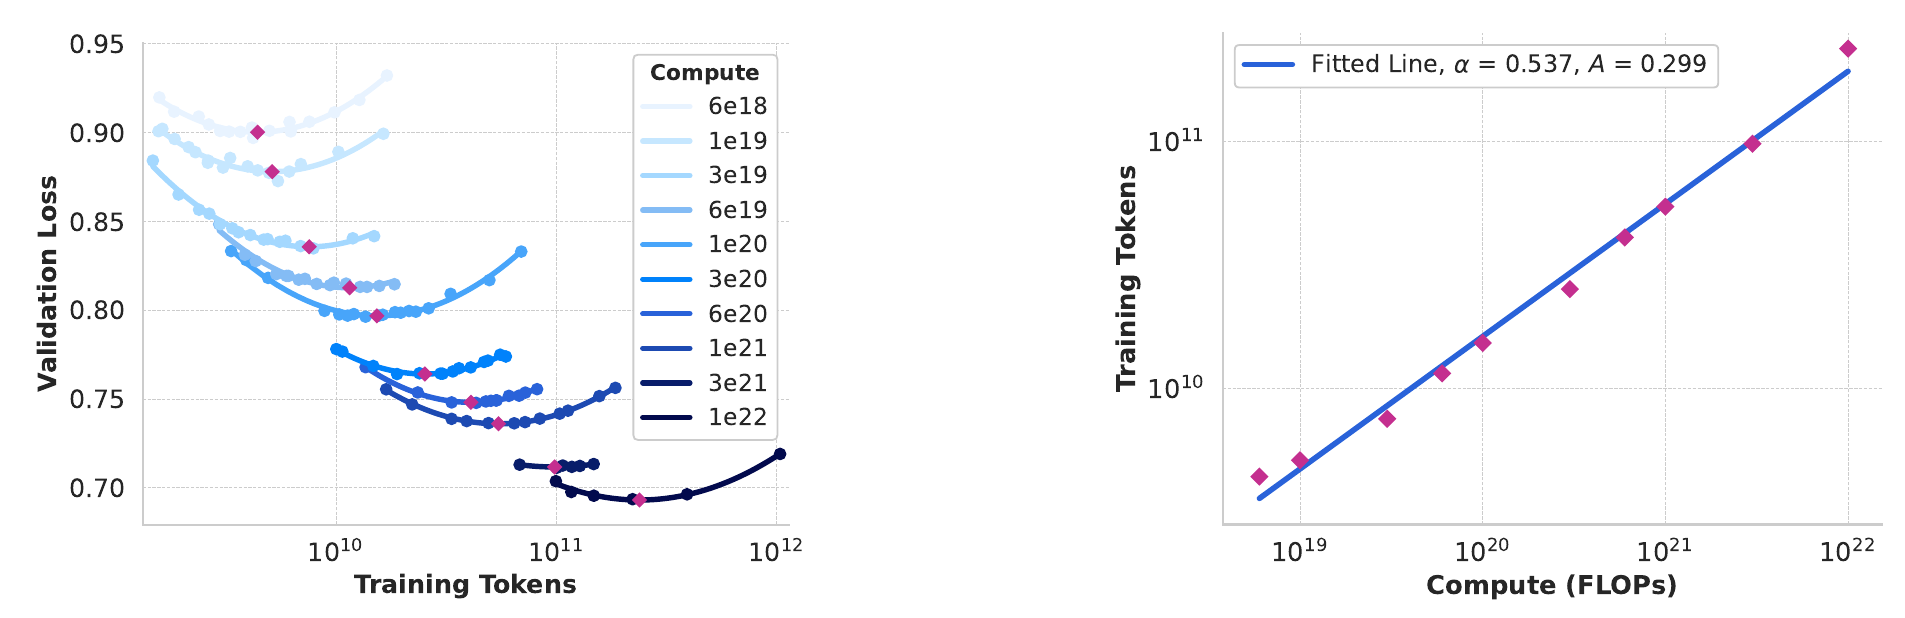
Each curve on the left is a fixed compute budget. For the same budget, a smaller model gets to see more tokens, and a larger model fewer; the bottom of each curve is the best allocation for that budget. The right plot connects the minima: the optimal number of training tokens follows a power law in compute :
Extrapolating to FLOPs, the report recommends "402B parameters and 16.55T tokens." One small detail here is worth computing yourself. Plugging in the figure's and gives about 16.3T tokens, close to the report's number. The main text, however, gives the parameters cut to two decimal places, , and those give about 10.5T. The exponent differs by only 0.007, yet after extrapolating across four orders of magnitude the results differ by about 50%. That is how sensitive scaling-law extrapolation is.
The authors also observe that the larger the compute budget, the flatter the bottom of the IsoFLOPs curve, so a model size slightly off the optimum matters little; they settled on 405B. The downstream predictions also worked well. On ARC Challenge, the two-step method extrapolated across four orders of magnitude and only slightly underestimated the final score.
Architecture: almost unchanged
Llama 3's architecture is much like Llama 2's, and the authors state plainly that the performance gains come mainly from data and scale. There are only four changes:
- Grouped-query attention (GQA): 8 key-value heads, shrinking the KV cache at inference.
- Document masking: when different documents are concatenated into one sequence, they are prevented from attending to each other. This matters little in standard pretraining, but it is important when continuing pretraining on very long sequences.
- A 128K vocabulary: tiktoken's 100K tokens plus 28K non-English tokens. English compression improves from 3.17 to 3.94 characters per token, so the same compute can "read" more text.
- RoPE base frequency raised to 500,000: to support longer contexts.
The 405B configuration has 126 layers, a hidden dimension of 16,384, and 128 attention heads.
Infrastructure: daily life with sixteen thousand GPUs
405B used up to 16K H100s at once. The model is split with 4D parallelism: tensor, pipeline, context, and data parallelism (FSDP). On 8K GPUs at sequence length 8K, BF16 model FLOPs utilization (MFU) is about 43%; scaling to 16K GPUs gives 41%; in the long-context stage, at sequence length 131K, it is 38%.
The most vivid part of the report is a failure tally. Over a 54-day observation period, training was interrupted 466 times: 47 were planned maintenance and 419 were unexpected. About 78% of the unexpected interruptions were confirmed or suspected hardware problems, most commonly the GPUs themselves and HBM3 memory. Even so, effective training time stayed above 90%.
This explains why the authors care so much about stability. With synchronous training, a problem on a single GPU can force the whole job to restart.
Pretraining recipe: three stages
- Initial pretraining: AdamW, peak learning rate , 8,000 warmup steps, cosine decay to . The batch starts small for stability, at 4M tokens and sequence length 4,096. At 252M tokens it doubles to 8M tokens and sequence length 8,192; at 2.87T tokens it doubles again to 16M. The authors say this recipe is very stable, with almost no loss spikes. The data mix was also adjusted along the way, for example adding more non-English data, upsampling math data, and adding more recent web data.
- Long-context pretraining: the context grows from 8K to 128K in six stages, about 800B tokens in total. The next stage begins only once short-context performance has fully recovered and the "needle in a haystack" test passes perfectly at the current length.
- Annealing: over the final 40 million tokens, the learning rate is linearly reduced to 0 while high-quality data is upsampled, and the checkpoints from the annealing phase are averaged to produce the final pretrained model.
The third point is the first "average" this note cares about. The report gives it one sentence, citing Polyak averaging, and does not say how many checkpoints were averaged or how much improvement it brought.
Post-training: six rounds of SFT plus DPO
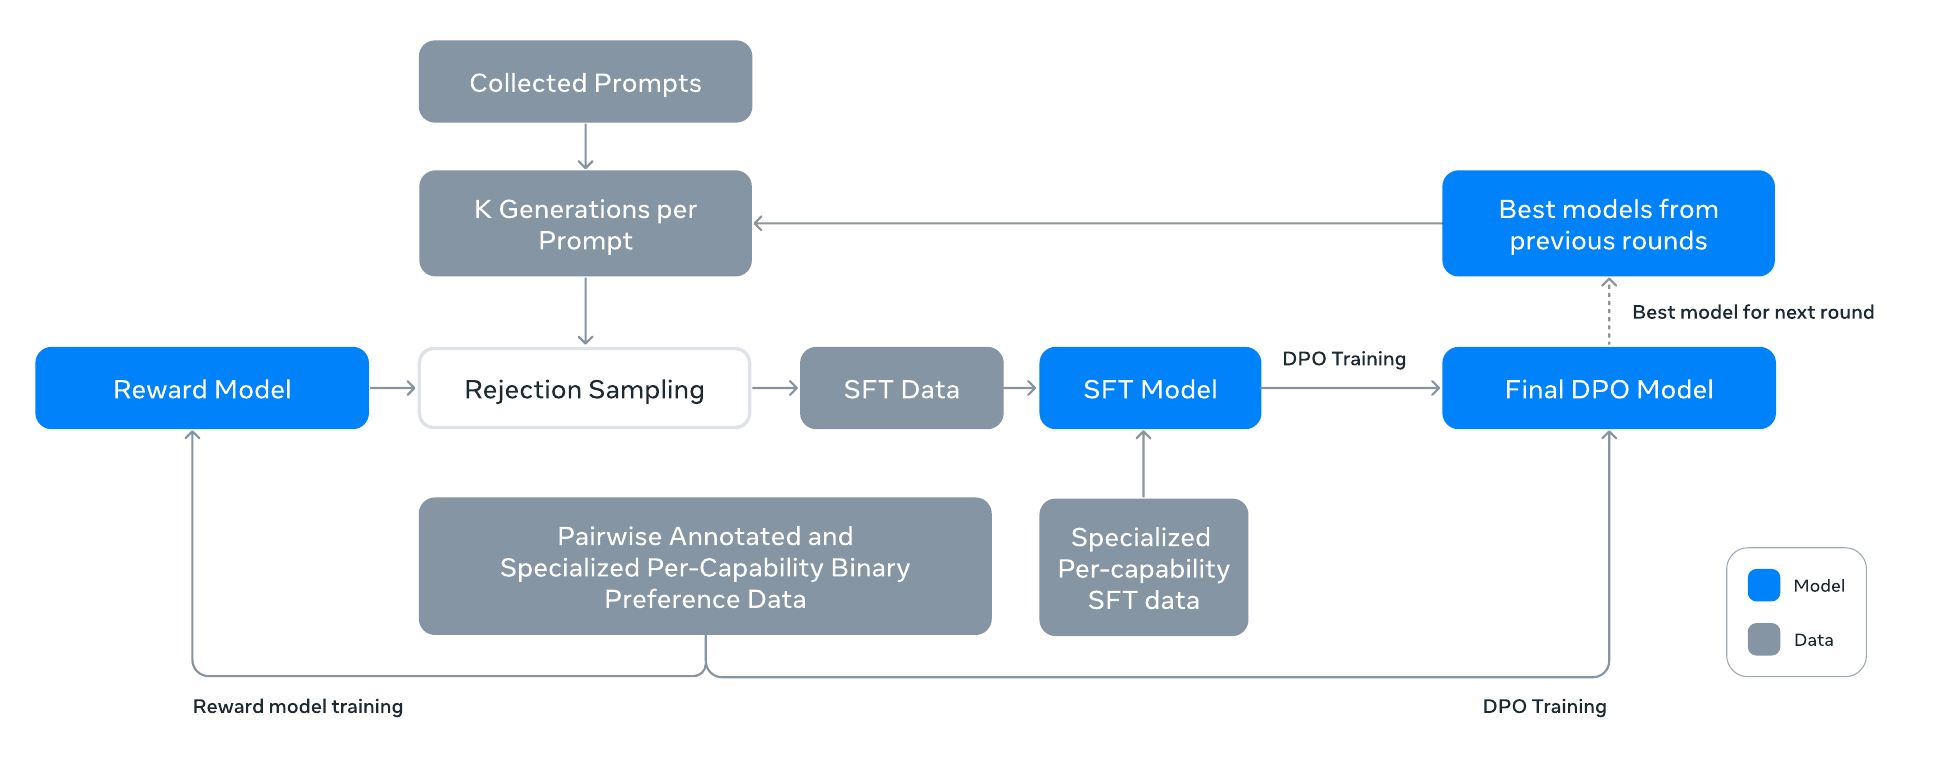
Read this figure from left to right, then follow the arrow across the top back to the start.
First, a reward model is trained on human-annotated preference data. Besides picking the better response, annotators sometimes edit it to make it better still, so one example can have three ranks: "edited > chosen > rejected." Then, for each prompt, 10 to 30 responses are sampled from the best model of the previous round, and the reward model picks the best one. This is rejection sampling, and the selected responses become SFT training data.
SFT uses a learning rate of for 8,500 to 9,000 steps. DPO follows, with learning rate and , plus two modifications:
- No loss on formatting tokens. The start and end markers of a conversation appear in both the good and the bad response, so DPO would be pushing their probabilities up and down at the same time. The authors found this causes repetitive output or abrupt endings.
- An added NLL regularization term, with coefficient 0.2, to keep the probability of the chosen responses from falling steadily.
The authors also tried PPO, but DPO needs less compute for large models and performs better on instruction-following evaluations such as IFEval.
The whole process repeats for six rounds, each with newly collected annotations and synthetic data generated by the latest model.
Then comes the second "average." At each of the reward-model, SFT, and DPO stages, the authors average models trained with different data versions or hyperparameters, citing none other than SWA and Model Soups. Again, the report gives no ablation.
Capabilities: expert branches and execution feedback
Most post-training data is model-generated, so quality control becomes central. The authors use Llama 3 8B for topic classification, estimate quality with two signals, reward-model scores and Llama's own assessment, then estimate difficulty, and finally deduplicate within semantic clusters, preferring samples of high quality and high difficulty.
Individual capabilities also get their own treatment. These two are the most representative.
Code. The authors branch off from the main pretraining run and continue pretraining on 1T tokens that are more than 85% code, producing a code expert used specifically to generate high-quality code-related data. In total there are more than 2.7 million synthetic examples.
The most interesting finding is that 8B and 70B improve markedly when trained on data generated by 405B, but training 405B on its own generated data does not help and can even make it worse. The authors' fix is to bring in execution feedback. Generated code has to pass syntax checks, static analysis, and unit tests written by the model itself; on failure, the error message is fed back with a request to fix it, and only dialogues that pass everything go into the training data. About 20% of solutions were wrong at first and then corrected themselves.
Long context. Doing SFT on short data alone noticeably degrades the long-context ability learned in pretraining. Human annotation of long documents is nearly infeasible, so synthetic data is used instead, including long-document QA, hierarchical summarization, and finding deleted code files. Ablations found that mixing just 0.1% synthetic long-context data into SFT is enough.
Discussion
Results
After post-training, 405B is roughly in the same class as the strongest closed models of the time, according to the report's Table 2:
| Benchmark | Llama 3 405B | GPT-4o | Claude 3.5 Sonnet |
|---|---|---|---|
| MMLU (5-shot) | 87.3 | 89.1 | 89.9 |
| MMLU-Pro (5-shot, CoT) | 73.3 | 74.0 | 77.0 |
| HumanEval (0-shot) | 89.0 | 90.2 | 92.0 |
| GSM8K (8-shot, CoT) | 96.8 | 96.1 | 96.4 |
| MATH (0-shot, CoT) | 73.8 | 76.6 | 71.1 |
| GPQA (0-shot, CoT) | 51.1 | 53.6 | 59.4 |
Most gaps are within a few points. It comes out slightly ahead on GSM8K and IFEval and clearly behind on GPQA.
Human evaluations point the same way. It roughly ties GPT-4 (the 0125 version); against GPT-4o and Claude 3.5 Sonnet it wins some and loses some, trailing Claude 3.5 Sonnet on code and reasoning. The authors also caution that human evaluation is strongly affected by details such as tone, structure, and length.
Inference: too big for one machine
Stored in BF16, 405B does not fit on a single machine with 8 H100s and has to span two machines with pipeline parallelism. The authors therefore apply FP8 quantization. What gets quantized is most of the weights and activations in the feedforward networks, which take up about half of inference compute time. The attention layers are not quantized, and neither are the first and last Transformer layers.
This part contains a very practical observation. Standard evaluations show FP8 roughly matching BF16, but the authors found that without an upper bound on the dynamic scaling factor, the model occasionally produced garbled responses that the evaluations did not catch. They switched to comparing the two by the distribution of reward-model scores over 100,000 responses, capped the scaling factor at 1200, and moved to row-wise quantization. FP8 raises prefill throughput by up to 50%.
Multimodality is only an experiment
Image, video, and speech capabilities come from attaching encoders and adapters alongside the frozen language model. Images come in through cross-attention layers, while speech is converted into token representations and fed in directly. When the report was written these models were still in development, and they were not released with version 3.1.
Vision post-training brings a third "average," and this time the report is more specific. Image SFT follows Model Soups. First run a hyperparameter sweep over different data subsets, learning rates, and weight decays, rank the results, then average the weights of the top ; itself is chosen by evaluating the averaged models. The authors say the averaged model is consistently better than the best single model found by grid search, and also less sensitive to hyperparameters. Vision DPO no longer keeps the reference model fixed, instead updating it every steps with an exponential moving average, which does better in human evaluations.
A rare passage in the report
The conclusion contains a passage rarely seen in technical reports. The authors say that, beyond technical problems, organizational decisions are also critical. For example, pretraining data was acquired and processed by a separate team that was explicitly required to keep the data free of benchmark contamination; human evaluations could be run and viewed only by a small group of researchers not involved in model development.
Things to keep in mind when reading this report
The report says a great deal about "what we did," but many decisions come without ablations. On why MoE was not used, or how much checkpoint averaging and model averaging each contributed, it offers only a conclusion or a single sentence. The sources and content of the pretraining data are not disclosed either, so third parties cannot reproduce it.
From a model-merging perspective, the report matters because it shows that "averaging" is already a standard step at large labs: average checkpoints during pretraining annealing, average models with different settings at every post-training stage, and average the top few models in the vision adapter's SFT as well. How to average, and how many models to average, were questions left for later papers.
Conclusion
Llama 3 went for more and cleaner data, larger scale, and a deliberately simple architecture and post-training. It showed that a model without MoE or PPO can stand alongside the best closed models of its time, as long as the data and scale are there.
The report also leaves plenty of practical details: use annealing to evaluate small datasets; 405B cannot live on its own generated data alone; long context needs only 0.1% synthetic data; and FP8 quantization should be judged by the distribution of reward scores, not by benchmark scores alone.
That reminder about organization carries particular weight a year later. When Llama 4 was released in April 2025, its high ranking on LMArena came from an experimental version specially tuned for conversation. LMArena then said that Meta's interpretation of its rules did not match what it expects from model providers, and updated its leaderboard policy. However carefully a technical report is written, the credibility of evaluation still depends on the organization holding the line.