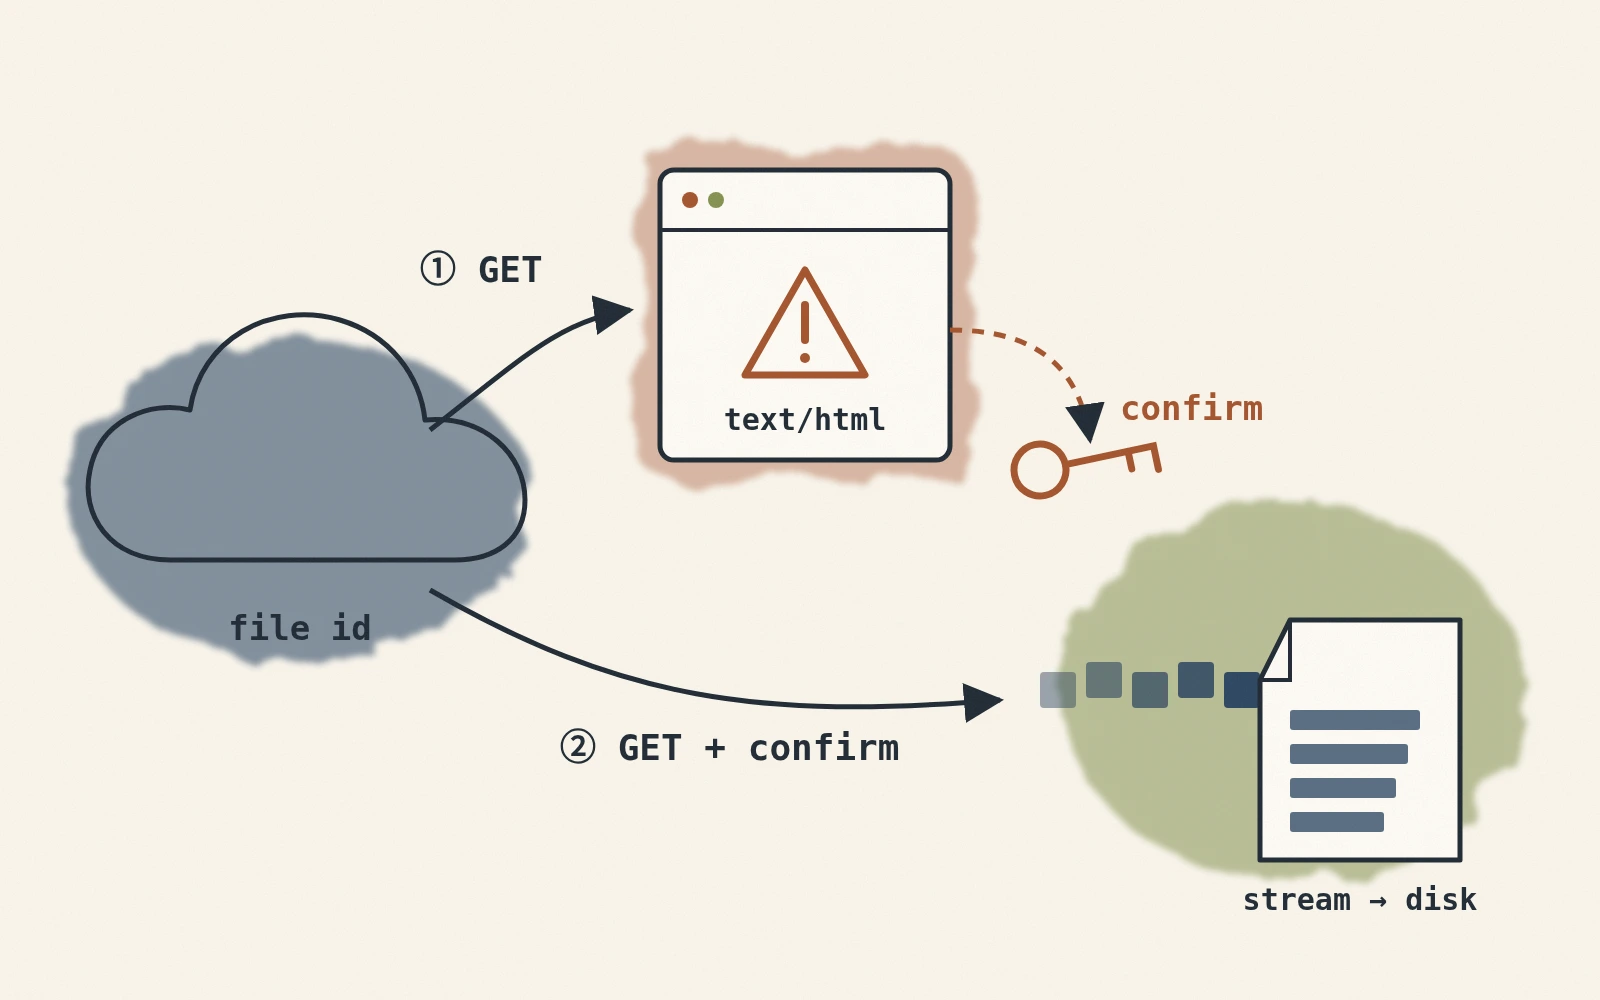
用 Python 下載 Google Drive 公開分享檔案時,程式有時會把病毒掃描確認頁的 HTML 存成檔案。這篇整理舊站使用的兩次請求流程,並說明程式應如何辨認真正的下載回應。
為什麼會只下載到 HTML?
向 Google Drive 網頁下載網址發送 GET 請求時,公開分享檔案有時會直接回傳檔案內容。
某些檔案會先出現病毒掃描提示頁,要求瀏覽器確認後才開始下載。觸發條件與頁面格式由 Google 控制,不能用固定檔案大小判斷。
瀏覽器可以按提示頁的確認按鈕;程式若沒有處理確認流程,就可能把 HTML 當成檔案。下載後還要確認最終回應確實帶有檔案標頭,避免寫入錯誤頁。
解題思路:二次請求
下載流程可以分成下列步驟:
- 第一次請求:帶著檔案 ID 對
https://docs.google.com/uc?export=download發送 GET。 - 檢查回應:若 HTTP Header 帶有
Content-Disposition,可以進入串流寫檔流程;若沒有,先檢查是否為下載確認頁,不要直接儲存成目標檔案。 - 擷取驗證參數:
- 從 cookies 中擷取:Google 可能在 cookie 中放置一個
download_warning_xxxxx類似的 key,裡面就是 token。例如:token = session.cookies.get('download_warning_xxxxx') - 從 HTML 中擷取:有時候 Google 不會把 token 放在 cookies,而是放在 HTML 的表單裡,例如:
這時候可以用 BeautifulSoup 把所有 hidden 欄位抓下來,包含
<form id="download-form" action="https://drive.usercontent.google.com/download" method="get" > <input type="hidden" name="confirm" value="t" /> ... </form>confirm或uuid等參數。
- 從 cookies 中擷取:Google 可能在 cookie 中放置一個
- 組合二次請求:帶入確認參數或表單欄位再次請求,再檢查 HTTP 狀態與下載標頭。確認頁結構可能調整,這種網頁解析方式只適合可公開取得的檔案。需要處理私人檔案或穩定的正式流程時,使用 Google Drive API 的檔案下載介面 與授權憑證。
程式碼實作
先安裝必要套件:
pip install requests tqdm beautifulsoup4
然後使用下列 Python 函式,傳入檔案 ID、要保存的檔名,以及下載後的目標資料夾,即可自動判斷是否需要二次請求並下載成功:
import os
import re
from urllib.parse import urljoin, urlparse
import requests
from tqdm import tqdm
from bs4 import BeautifulSoup

def download_from_google(file_id: str, file_name: str, target: str = "."):
    """
    Downloads a file from Google Drive, handling potential confirmation tokens for large files.

    Args:
        file_id (str):
            The ID of the file to download from Google Drive.
        file_name (str):
            The name to save the downloaded file as.
        target (str, optional):
            The directory to save the file in. Defaults to the current directory (".").

    Raises:
        Exception: If the download fails or the file cannot be created.

    Notes:
        This function handles both small and large files. For large files, it automatically processes
        Google's confirmation token to bypass warnings about virus scans or file size limits.

    Example:
        Download a file to the current directory:
            download_from_google(
                file_id="xxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx",
                file_name="example_file.txt"
            )

        Download a file to a specific directory:
            download_from_google(
                file_id="xxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx",
                file_name="example_file.txt",
                target="./downloads"
            )
    """
    # 第一次嘗試:docs.google.com/uc?export=download&id=檔案ID
    base_url = "https://docs.google.com/uc"
    session = requests.Session()
    params = {
        "export": "download",
        "id": file_id
    }
    response = session.get(base_url, params=params, stream=True, timeout=(10, 60))

    # 如果已經出現 Content-Disposition,代表直接拿到檔案
    if "content-disposition" not in response.headers:
        # 先嘗試從 cookies 拿 token
        token = None
        for k, v in response.cookies.items():
            if k.startswith("download_warning"):
                token = v
                break

        # 如果 cookies 沒有,就從 HTML 解析
        if not token:
            soup = BeautifulSoup(response.text, "html.parser")
            # 常見情況:HTML 裡面有一個 form#download-form
            download_form = soup.find("form", {"id": "download-form"})
            if download_form and download_form.get("action"):
                # 將 action 裡的網址抓出來,可能是 drive.usercontent.google.com/download
                download_url = urljoin(response.url, download_form["action"])
                if urlparse(download_url).hostname not in {
                    "docs.google.com", "drive.google.com", "drive.usercontent.google.com"
                }:
                    raise RuntimeError("Unexpected Google Drive download host")
                # 收集所有 hidden 欄位
                hidden_inputs = download_form.find_all(
                    "input", {"type": "hidden"})
                form_params = {}
                for inp in hidden_inputs:
                    if inp.get("name") and inp.get("value") is not None:
                        form_params[inp["name"]] = inp["value"]

                # 用這些參數去重新 GET
                # 注意:原本 action 可能只是相對路徑,這裡直接用完整網址
                response = session.get(
                    download_url, params=form_params, stream=True, timeout=(10, 60))
            else:
                # 或者有些情況是直接在 HTML 裡 search confirm=xxx
                match = re.search(r'confirm=([0-9A-Za-z-_]+)', response.text)
                if match:
                    token = match.group(1)
                    # 帶上 confirm token 再重新請求 docs.google.com
                    params["confirm"] = token
                    response = session.get(
                        base_url, params=params, stream=True, timeout=(10, 60))
                else:
                    raise Exception("無法在回應中找到下載連結或確認參數,下載失敗。")

        else:
            # 直接帶上 cookies 抓到的 token 再打一次
            params["confirm"] = token
            response = session.get(base_url, params=params, stream=True, timeout=(10, 60))

    # 確保下載目錄存在
    response.raise_for_status()
    if "content-disposition" not in response.headers:
        raise RuntimeError("Google Drive did not return a downloadable file")
    if not file_name or file_name in {".", ".."} or os.path.basename(file_name) != file_name:
        raise ValueError("file_name must be a filename, not a path")

    os.makedirs(target, exist_ok=True)
    file_path = os.path.join(target, file_name)

    # 開始把檔案 chunk 寫到本地,附帶進度條
    try:
        total_size = int(response.headers.get('content-length', 0))
        with open(file_path, "wb") as f, tqdm(
            desc=file_name,
            total=total_size,
            unit="B",
            unit_scale=True,
            unit_divisor=1024,
        ) as bar:
            for chunk in response.iter_content(chunk_size=32768):
                if chunk:
                    f.write(chunk)
                    bar.update(len(chunk))

        print(f"File successfully downloaded to: {file_path}")

    except Exception as e:
        raise Exception(f"File download failed: {e}")
使用方式
假設檔案 ID 為YOUR_FILE_ID,要下載為 big_model.onnx 並存在 ./models 目錄下,只需要這樣呼叫:
download_from_google(
    file_id="YOUR_FILE_ID",
    file_name="big_model.onnx",
    target="./models"
)
完成後,即可在 ./models 資料夾下看到成功下載的 big_model.onnx,並且能在命令列上看到下載進度。
指令列工具
或是你希望可以直接用指令列來操作,那可以加一段程式來包裝一下:
from download_from_google import download_from_google
import argparse

def main():
    parser = argparse.ArgumentParser(description="Download files from Google Drive.")
    parser.add_argument("--file-id", required=True, help="Google Drive file ID.")
    parser.add_argument("--file-name", required=True, help="Output file name.")
    parser.add_argument("--target", default=".", help="Output directory. Defaults to current folder.")
    args = parser.parse_args()

    download_from_google(file_id=args.file_id, file_name=args.file_name, target=args.target)

if __name__ == "__main__":
    main()
將上述程式碼儲存為 download_from_google_cli.py,就可以直接在命令列執行:
python download_from_google_cli.py \
 --file-id YOUR_FILE_ID \
 --file-name big_model.onnx \
 --target ./models
若網頁回應仍是確認頁或錯誤頁,程式應直接報錯,避免留下副檔名正確、內容卻是 HTML 的檔案。
原站曾以 70 MB 與 900 MB 的公開檔案試跑;這只記錄當時的網頁行為,不能保證其他權限、檔案類型或後續介面版本都相同。