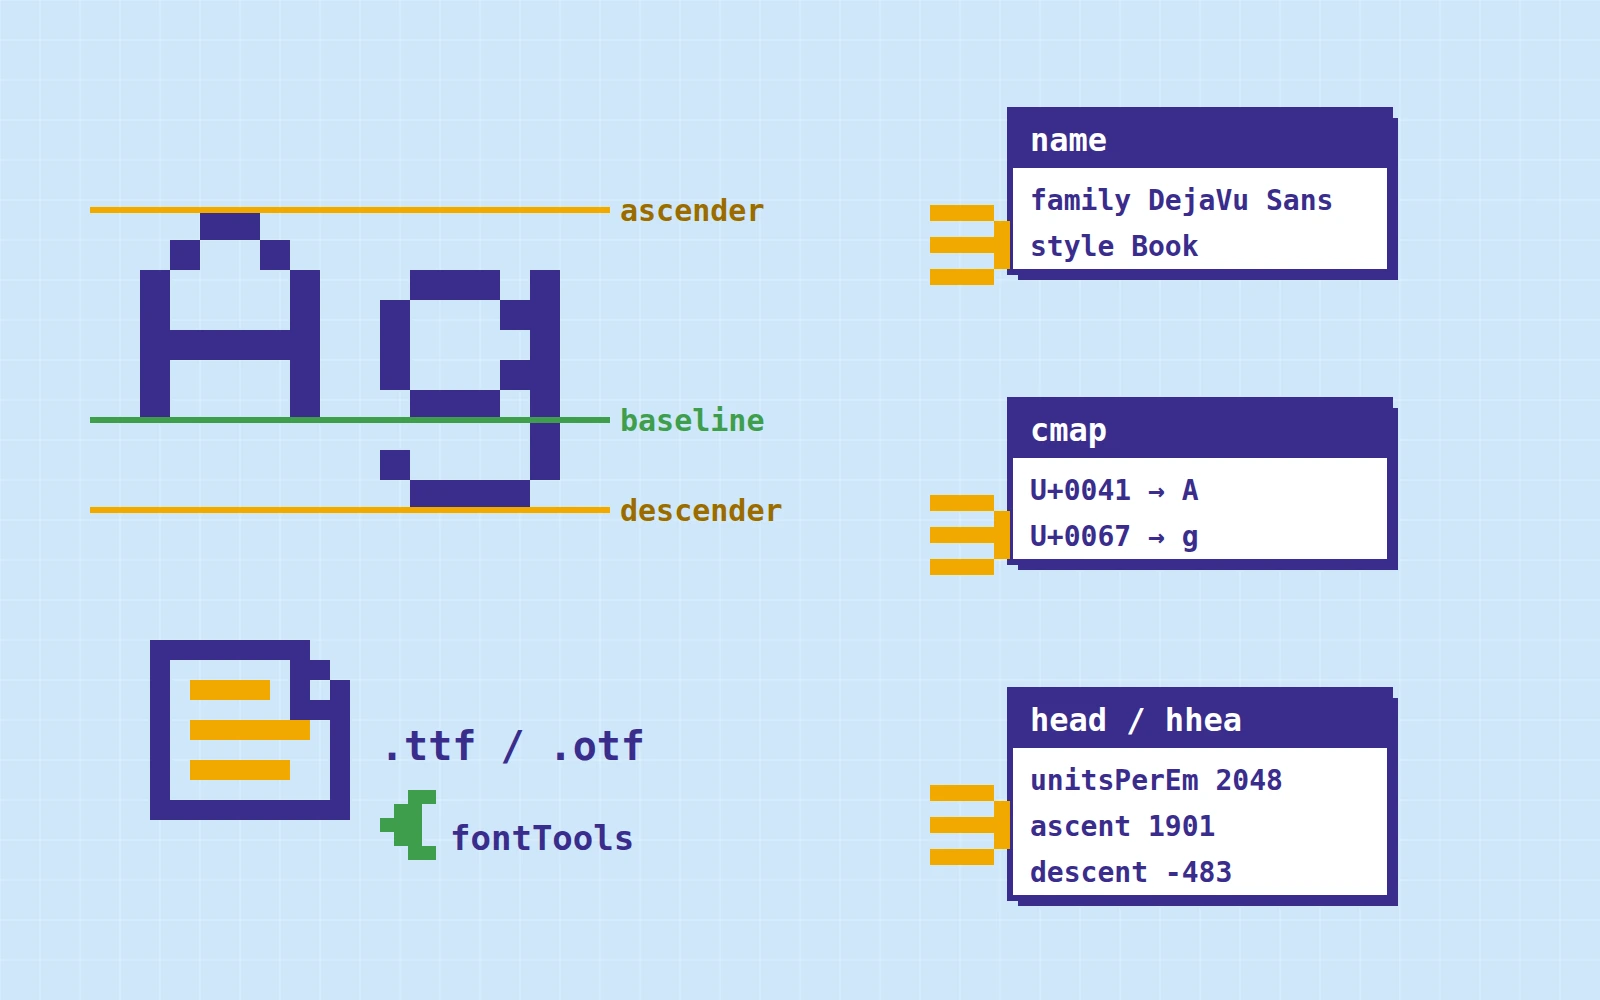
フォントファイルにはグリフに加え、ファミリー名、バージョン、ウェイト、文字の対応関係、組版のメトリクスが含まれます。多数の TTF/OTF ファイルを比較するなら、ビューアで一つずつ開くより、表を読み出して構造化した情報として保存すると確認しやすくなります。この記事では fontTools を使用します。
fontTools のインストール
fontTools の文書にある TTFont は、TTF/OTF の表を読み取ります。一部の任意表が存在しない場合があるため、コードでは使用前に確認します。
まず、以下のコマンドで fontTools をインストールします:
pip install fonttools
インストールが完了したら、プログラムを実行できます。
実装のポイント
コードを使う前に、まずは実装のポイントを確認しましょう:
-
不要な制御文字の削除 (
remove_control_characters)この関数は、文字列内の制御文字や目に見えない文字を取り除くために使用されます。これらの文字は後続の処理を妨げる可能性があるため、最初に削除する必要があります。任意の
unicodedata正規化は等価な Unicode 表現を揃えますが、すべての結合文字列が一文字になるわけではありません。
-
フォント情報の抽出 (
extract_font_info)フォントからさまざまな情報を取得し、整理して、読みやすい構造化された辞書形式で出力します。これには多数のキーが含まれており、それぞれの説明は以下の通りです:
fileName: フォントファイルのシステム内のパス。tables: フォントファイル内で利用可能なすべてのテーブルをリスト表示。nameTable:nameIDをインデックスとして持つ原始的な name table。nameTableReadable: よく使われるnameID(例えば、フォントファミリーやバージョン)をより読みやすいキーにマッピング。cmapTable: さまざまなエンコーディング(platformID、platEncID)とグリフ名の対応関係。headTable: フォントの基本的なパラメーター情報(例:unitsPerEm、xMin、yMinなど)。hheaTable: 水平レイアウト情報(上端(ascent)、下端(descent)、行間(lineGap)など)。OS2Table: フォントの太さ(usWeightClass)、フォントの幅(usWidthClass)、埋め込み制限(fsType)など。postTable: PostScript に関連する情報(固定幅フォントかどうか(isFixedPitch)、傾斜角度(italicAngle)など)。layoutMetrics: 複数のテーブルを統合したレイアウトの計測情報(バウンディングボックス、unitsPerEm、行間など)。summary: フォントの概要(フォントファミリー(fontFamily)、サブファミリー(fontSubfamily)、バージョン情報(version)、フォントの太さ(weightClass)、斜体かどうか(isItalic))を素早く確認できる情報。
中でも重要なのは cmapTable です。このテーブルは、さまざまなエンコーディングと文字の対応関係を示しており、以下のコードでは、このテーブルを処理して、エンコーディングを読みやすいプラットフォーム名とエンコーディング名に変換しています:
-
プラットフォーム名 (
platform_name)platformIDは、フォントがサポートしているプラットフォームを示します。よく使われるプラットフォームコードは以下の通りです:0: Unicode(一般的なフォント標準)1: Macintosh(Mac システム専用フォント)3: Windows(Windows システム専用フォント)
プログラム内では、これらのコードを辞書を使って文字列に変換します:
platform_name = {
    0: 'Unicode',
    1: 'Macintosh',
    3: 'Windows'
}.get(cmap.platformID, f"Platform {cmap.platformID}")
このコードは、
platformIDが辞書内にあるか確認し、対応する値が見つかればその名前(例えば'Unicode')を返します。もし見つからない場合は、Platform {cmap.platformID}を返して、辞書にないカスタムプラットフォームコードを処理します。 -
エンコーディング名 (
encoding_name)フォント内のエンコーディング方式は、
platformIDとplatEncIDによって決まります。よくある組み合わせとその意味は以下の通りです:(0, 0): Unicode 1.0(0, 3): Unicode 2.0+(0, 4): Unicode 2.0+ with BMP(基本多言語面)(1, 0): Mac Roman(Macintosh のローマ字コード)(3, 1): Windows Unicode BMP(Windows の基本多言語面コード)(3, 10): Windows Unicode Full(Windows の完全 Unicode コード)
プログラム内では、これらの組み合わせをネストされた辞書に格納し、
(platformID, platEncID)のタプルを使って検索します:encoding_name = { (0, 0): 'Unicode 1.0', (0, 3): 'Unicode 2.0+', (0, 4): 'Unicode 2.0+ with BMP', (1, 0): 'Mac Roman', (3, 1): 'Windows Unicode BMP', (3, 10): 'Windows Unicode Full' }.get((cmap.platformID, cmap.platEncID), f"Encoding {cmap.platEncID}")対応する組み合わせが見つかれば、その文字列を返します。見つからない場合は、デフォルトで
Encoding {cmap.platEncID}を返し、未知のエンコーディングを処理します。
コード
以下は完全なコードです。出力された情報を JSON 形式で保存することができ、その後の分析や追跡に役立てることができます。
import re
import unicodedata
from pathlib import Path
from typing import List, Union
from fontTools.ttLib import TTFont
def load_ttfont(font_path: Union[str, Path], **kwargs) -> TTFont:
"""Load a TrueType font file."""
if isinstance(font_path, Path):
font_path = str(font_path)
return TTFont(font_path, **kwargs)
def remove_control_characters(text: str, normalize: bool = True) -> str:
"""
Remove control characters and invisible formatting characters from a string.
Args:
text (str): The input string.
normalize (bool): Whether to normalize the text to remove inconsistencies.
Returns:
str: The sanitized string with control and invisible characters removed.
"""
# Remove basic control characters (C0 and C1 control codes)
sanitized = re.sub(r'[\x00-\x1F\x7F-\x9F]', '', text)
# Remove specific Unicode control and invisible formatting characters
sanitized = re.sub(
r'[\u200B-\u200F\u2028-\u202F\u2060-\u206F]', '', sanitized)
# Remove directional formatting characters (optional, adjust if needed)
sanitized = re.sub(r'[\u202A-\u202E]', '', sanitized)
# Optionally, normalize the text to remove any leftover inconsistencies
if normalize:
sanitized = unicodedata.normalize('NFKC', sanitized)
return sanitized
def extract_font_info(
font_path: Union[str, Path],
normalize: bool = True
) -> dict:
"""Extract detailed metadata and structural information from a font file.
Args:
font_path (Union[str, Path]): Path to the font file.
Returns:
dict: A dictionary containing font metadata and tables, including:
- fileName (str): Path to the font file.
- tables (list): List of available tables in the font.
- nameTable (dict): Raw name table values, keyed by nameID.
- nameTableReadable (dict): Readable name table with keys:
* copyright (str): Copyright information.
* fontFamily (str): Font family name.
* fontSubfamily (str): Font subfamily name.
* uniqueID (str): Unique identifier for the font.
* fullName (str): Full font name.
* version (str): Font version string.
* postScriptName (str): PostScript name.
- cmapTable (dict): Character-to-glyph mappings, keyed by encoding.
- cmapTableIndex (list): List of encoding descriptions.
- headTable (dict): Font header table with keys:
* unitsPerEm (int): Units per em.
* xMin (int): Minimum x-coordinate of the glyph bounding box.
* yMin (int): Minimum y-coordinate of the glyph bounding box.
* xMax (int): Maximum x-coordinate of the glyph bounding box.
* yMax (int): Maximum y-coordinate of the glyph bounding box.
- hheaTable (dict): Horizontal header table with keys:
* ascent (int): Typographic ascent.
* descent (int): Typographic descent.
* lineGap (int): Line gap.
- OS2Table (dict): OS/2 table with keys:
* usWeightClass (int): Weight class.
* usWidthClass (int): Width class.
* fsType (int): Embedding restrictions.
- postTable (dict): PostScript table with keys:
* isFixedPitch (bool): Whether the font is monospaced.
* italicAngle (float): Italic angle of the font.
- layoutMetrics (dict): Font layout metrics with keys:
* unitsPerEm (int): Units per em.
* boundingBox (dict): Bounding box coordinates:
- xMin (int): Minimum x-coordinate.
- yMin (int): Minimum y-coordinate.
- xMax (int): Maximum x-coordinate.
- yMax (int): Maximum y-coordinate.
* ascent (int): Typographic ascent.
* descent (int): Typographic descent.
* lineGap (int): Line gap.
- summary (dict): High-level font summary with keys:
* fontFamily (str): Font family name.
* fontSubfamily (str): Font subfamily name.
* version (str): Font version.
* weightClass (int): Weight class.
* isItalic (bool): Whether the font is italic.
"""
if isinstance(font_path, Path):
font_path = str(font_path)
font = TTFont(font_path)
font_info = {}
# File name and available tables
font_info['fileName'] = font_path
font_info['tables'] = list(font.keys())
# Parse name table
name_table = {}
for record in font['name'].names:
try:
raw_string = record.string.decode('utf-16-be').strip()
clean_string = remove_control_characters(raw_string, normalize)
name_table[record.nameID] = clean_string
except UnicodeDecodeError:
name_table[record.nameID] = remove_control_characters(
record.string.decode(errors='ignore'), normalize)
font_info['nameTable'] = name_table
# Readable name table for common nameIDs
name_table_readable = {
'copyright': name_table.get(0, ''),
'fontFamily': name_table.get(1, ''),
'fontSubfamily': name_table.get(2, ''),
'uniqueID': name_table.get(3, ''),
'fullName': name_table.get(4, ''),
'version': name_table.get(5, ''),
'postScriptName': name_table.get(6, ''),
}
font_info['nameTableReadable'] = {
k: remove_control_characters(v, normalize)
for k, v in name_table_readable.items()
}
# Parse cmap table
cmap_table = {}
cmap_table_index = []
for cmap in font['cmap'].tables:
platform_name = {
0: 'Unicode',
1: 'Macintosh',
3: 'Windows'
}.get(cmap.platformID, f"Platform {cmap.platformID}")
encoding_name = {
    (0, 0): 'Unicode 1.0',
    (0, 3): 'Unicode 2.0+',
    (0, 4): 'Unicode 2.0+ with BMP',
    (1, 0): 'Mac Roman',
    (3, 1): 'Windows Unicode BMP',
    (3, 10): 'Windows Unicode Full'
}.get((cmap.platformID, cmap.platEncID), f"Encoding {cmap.platEncID}")
cmap_entries = {}
for codepoint, glyph_name in cmap.cmap.items():
char = chr(codepoint)
cmap_entries[remove_control_characters(char, normalize)] = \
remove_control_characters(glyph_name, normalize)
key = f"{platform_name}, {encoding_name}"
cmap_table[key] = cmap_entries
cmap_table_index.append(key)
font_info['cmapTable'] = cmap_table
font_info['cmapTableIndex'] = cmap_table_index
# Parse head table
head = font['head']
head_table = {
'unitsPerEm': head.unitsPerEm,
'xMin': head.xMin,
'yMin': head.yMin,
'xMax': head.xMax,
'yMax': head.yMax,
}
font_info['headTable'] = head_table
# Parse hhea table
hhea = font['hhea']
hhea_table = {
'ascent': hhea.ascent,
'descent': hhea.descent,
'lineGap': hhea.lineGap,
}
font_info['hheaTable'] = hhea_table
# Parse OS/2 table
os2 = font['OS/2']
os2_table = {
'usWeightClass': os2.usWeightClass,
'usWidthClass': os2.usWidthClass,
'fsType': os2.fsType,
}
font_info['OS2Table'] = os2_table
# Parse post table
post = font['post']
post_table = {
'isFixedPitch': post.isFixedPitch,
'italicAngle': post.italicAngle,
}
font_info['postTable'] = post_table
# Combine layout-related metrics
font_info['layoutMetrics'] = {
'unitsPerEm': head_table['unitsPerEm'],
'boundingBox': {
'xMin': head_table['xMin'],
'yMin': head_table['yMin'],
'xMax': head_table['xMax'],
'yMax': head_table['yMax']
},
'ascent': hhea_table['ascent'],
'descent': hhea_table['descent'],
'lineGap': hhea_table['lineGap']
}
# Font summary
font_info['summary'] = {
'fontFamily': name_table_readable['fontFamily'],
'fontSubfamily': name_table_readable['fontSubfamily'],
'version': name_table_readable['version'],
'weightClass': os2.usWeightClass,
'isItalic': post_table['italicAngle'] != 0
}
return font_info
出力結果の例
OcrB-Regular.ttf フォントファイルを例に、関数を呼び出して JSON ファイルに出力するコードは以下の通りです:
import json

font_infos = extract_font_info('OcrB-Regular.ttf')
json.dump(font_infos, open('OcrB-Regular-Info.json', 'w'),
          indent=2, ensure_ascii=False)
出力結果は以下のようになります:
{
"fileName": "/path/to/your/folder/OcrB-Regular.ttf",
"tables": [
"GlyphOrder",
"head",
"hhea",
"maxp",
"OS/2",
"hmtx",
"hdmx",
"cmap",
"fpgm",
"prep",
"cvt ",
"loca",
"glyf",
"name",
"post"
],
"nameTable": {
"0": "This is a copyrighted typeface program",
"1": "OcrB",
"2": "Regular",
"3": "Altsys Fontographer 3.5 OcrB Regular",
"4": "OcrB Regular",
"5": "Altsys Fontographer 3.5 4/15/93",
"6": "OcrB Regular"
},
"nameTableReadable": {
"copyright": "This is a copyrighted typeface program",
"fontFamily": "OcrB",
"fontSubfamily": "Regular",
"uniqueID": "Altsys Fontographer 3.5 OcrB Regular",
"fullName": "OcrB Regular",
"version": "Altsys Fontographer 3.5 4/15/93",
"postScriptName": "OcrB Regular"
},
"cmapTable": {
"Unicode, Unicode 1.0": {
" ": "nonbreakingspace",
"!": "exclam",
"\"": "quotedbl",
"#": "numbersign",
"$": "dollar",
"%": "percent",
"&": "ampersand",
"'": "quotesingle",
"(": "parenleft",
")": "parenright",
"*": "asterisk",
"+": "plus",
",": "comma",
"-": "hyphen",
".": "period",
"/": "slash",
"0": "zero",
"1": "one",
"2": "two",
"3": "three",
"4": "four",
"5": "five",
"6": "six",
"7": "seven",
"8": "eight",
"9": "nine",
":": "colon",
";": "semicolon",
"<": "less",
"=": "equal",
">": "greater",
"?": "question",
"@": "at",
"A": "A",
"B": "B",
"C": "C",
"D": "D",
"E": "E",
"F": "F",
"G": "G",
"H": "H",
"I": "I",
"J": "J",
"K": "K",
"L": "L",
"M": "M",
"N": "N",
"O": "O",
"P": "P",
"Q": "Q",
"R": "R",
"S": "S",
"T": "T",
"U": "U",
"V": "V",
"W": "W",
"X": "X",
"Y": "Y",
"Z": "Z",
"[": "bracketleft",
"\\": "backslash",
"]": "bracketright",
"^": "asciicircum",
"_": "underscore",
"`": "grave",
"a": "a",
"b": "b",
"c": "c",
"d": "d",
"e": "e",
"f": "f",
"g": "g",
"h": "h",
"i": "i",
"j": "j",
"k": "k",
"l": "l",
"m": "m",
"n": "n",
"o": "o",
"p": "p",
"q": "q",
"r": "r",
"s": "zcaron",
"t": "t",
"u": "u",
"v": "v",
"w": "w",
"x": "x",
"y": "y",
"z": "z",
"{": "braceleft",
"|": "bar",
"}": "braceright",
"¡": "exclamdown",
"¢": "cent",
"£": "sterling",
"¤": "currency",
"¥": "yen",
"§": "section",
" ̈": "dieresis",
"«": "guillemotleft",
"": "hyphen",
" ̄": "macron",
" ́": "acute",
"·": "periodcentered",
" ̧": "cedilla",
"»": "guillemotright",
"¿": "questiondown",
"À": "Agrave",
"Á": "Aacute",
"Â": "Acircumflex",
"Ã": "Atilde",
"Ä": "Adieresis",
"Å": "Aring",
"Æ": "AE",
"Ç": "Ccedilla",
"È": "Egrave",
"É": "Eacute",
"Ê": "Ecircumflex",
"Ë": "Edieresis",
"Ì": "Igrave",
"Í": "Iacute",
"Î": "Icircumflex",
"Ï": "Idieresis",
"Ð": "Eth",
"Ñ": "Ntilde",
"Ò": "Ograve",
"Ó": "Oacute",
"Ô": "Ocircumflex",
"Õ": "Otilde",
"Ö": "Odieresis",
"×": ".null",
"Ø": "Oslash",
"Ù": "Ugrave",
"Ú": "Uacute",
"Û": "Ucircumflex",
"Ü": "Udieresis",
"Ý": "Yacute#1",
"Þ": "Thorn",
"ß": "germandbls",
"à": "agrave",
"á": "aacute",
"â": "acircumflex",
"ã": "atilde",
"ä": "adieresis",
"å": "aring",
"æ": "ae",
"ç": "ccedilla",
"è": "egrave",
"é": "eacute",
"ê": "ecircumflex",
"ë": "edieresis",
"ì": "igrave",
"í": "iacute",
"î": "icircumflex",
"ï": "idieresis",
"ð": "Yacute",
"ñ": "ntilde",
"ò": "ograve",
"ó": "oacute",
"ô": "ocircumflex",
"õ": "otilde",
"ö": "odieresis",
"ø": "oslash",
"ù": "ugrave",
"ú": "uacute",
"û": "ucircumflex",
"ü": "udieresis",
"ý": "yacute",
"þ": "thorn",
"ÿ": "ydieresis",
"ı": "dotlessi",
"Ł": "Lslash",
"ł": "lslash",
"Œ": "OE",
"œ": "oe",
"Š": "Scaron",
"š": "scaron",
"Ÿ": "Ydieresis",
"Ž": "Zcaron",
"ʺ": "hungarumlaut",
"ˆ": "circumflex",
"ˇ": "caron",
"ˉ": "macron",
" ̆": "breve",
" ̇": "dotaccent",
" ̊": "ring",
" ̨": "ogonek",
" ̃": "tilde",
"–": "endash",
"—": "emdash",
"‘": "quoteleft",
"‚": "quotesinglbase",
"“": "quotedblleft",
"”": "quotedblright",
"„": "quotedblbase",
"†": "dagger",
"‡": "daggerdbl",
"...": "ellipsis",
"‹": "guilsinglleft",
"›": "guilsinglright",
"−": "minus",
"∙": "periodcentered"
},
"Macintosh, Mac Roman": {
"": "udieresis",
" ": "dagger",
"!": "exclam",
"\"": "quotedbl",
"#": "numbersign",
"$": "dollar",
"%": "percent",
"&": "ampersand",
"'": "quotesingle",
"(": "parenleft",
")": "parenright",
"*": "asterisk",
"+": "plus",
",": "comma",
"-": "hyphen",
".": "period",
"/": "slash",
"0": "zero",
"1": "one",
"2": "two",
"3": "three",
"4": "four",
"5": "five",
"6": "six",
"7": "seven",
"8": "eight",
"9": "nine",
":": "colon",
";": "semicolon",
"<": "less",
"=": "equal",
">": "greater",
"?": "question",
"@": "at",
"A": "A",
"B": "B",
"C": "C",
"D": "D",
"E": "E",
"F": "F",
"G": "G",
"H": "H",
"I": "I",
"J": "J",
"K": "K",
"L": "L",
"M": "M",
"N": "N",
"O": "O",
"P": "P",
"Q": "Q",
"R": "R",
"S": "S",
"T": "T",
"U": "U",
"V": "V",
"W": "W",
"X": "X",
"Y": "Y",
"Z": "Z",
"[": "bracketleft",
"\\": "backslash",
"]": "bracketright",
"^": "asciicircum",
"_": "underscore",
"`": "grave",
"a": "a",
"b": "b",
"c": "c",
"d": "d",
"e": "e",
"f": "f",
"g": "g",
"h": "h",
"i": "i",
"j": "j",
"k": "k",
"l": "l",
"m": "m",
"n": "n",
"o": "o",
"p": "p",
"q": "q",
"r": "r",
"s": "s",
"t": "t",
"u": "u",
"v": "v",
"w": "w",
"x": "x",
"y": "y",
"z": "z",
"{": "braceleft",
"|": "bar",
"}": "braceright",
"¢": "cent",
"£": "sterling",
"¤": "section",
"§": "germandbls",
"«": "acute",
"¬": "dieresis",
"®": "AE",
" ̄": "Oslash",
" ́": "yen",
"3⁄4": "ae",
"¿": "oslash",
"À": "questiondown",
"Á": "exclamdown",
"Ç": "guillemotleft",
"È": "guillemotright",
"É": "ellipsis",
"Ê": "nonbreakingspace",
"Ë": "Agrave",
"Ì": "Atilde",
"Í": "Otilde",
"Î": "OE",
"Ï": "oe",
"Ð": "endash",
"Ñ": "emdash",
"Ò": "quotedblleft",
"Ó": "quotedblright",
"Ô": "quoteleft",
"Ø": "ydieresis",
"Ù": "Ydieresis",
"Û": "currency",
"Ü": "guilsinglleft",
"Ý": "guilsinglright",
"à": "daggerdbl",
"á": "periodcentered",
"â": "quotesinglbase",
"ã": "quotedblbase",
"å": "Acircumflex",
"æ": "Ecircumflex",
"ç": "Aacute",
"è": "Edieresis",
"é": "Egrave",
"ê": "Iacute",
"ë": "Icircumflex",
"ì": "Idieresis",
"í": "Igrave",
"î": "Oacute",
"ï": "Ocircumflex",
"ñ": "Ograve",
"ò": "Uacute",
"ó": "Ucircumflex",
"ô": "Ugrave",
"õ": "dotlessi",
"ö": "circumflex",
"÷": "tilde",
"ø": "macron",
"ù": "breve",
"ú": "dotaccent",
"û": "ring",
"ü": "cedilla",
"ý": "hungarumlaut",
"þ": "ogonek",
"ÿ": "caron"
},
"Windows, Windows Unicode BMP": {
" ": "nonbreakingspace",
"!": "exclam",
"\"": "quotedbl",
"#": "numbersign",
"$": "dollar",
"%": "percent",
"&": "ampersand",
"'": "quotesingle",
"(": "parenleft",
")": "parenright",
"*": "asterisk",
"+": "plus",
",": "comma",
"-": "hyphen",
".": "period",
"/": "slash",
"0": "zero",
"1": "one",
"2": "two",
"3": "three",
"4": "four",
"5": "five",
"6": "six",
"7": "seven",
"8": "eight",
"9": "nine",
":": "colon",
";": "semicolon",
"<": "less",
"=": "equal",
">": "greater",
"?": "question",
"@": "at",
"A": "A",
"B": "B",
"C": "C",
"D": "D",
"E": "E",
"F": "F",
"G": "G",
"H": "H",
"I": "I",
"J": "J",
"K": "K",
"L": "L",
"M": "M",
"N": "N",
"O": "O",
"P": "P",
"Q": "Q",
"R": "R",
"S": "S",
"T": "T",
"U": "U",
"V": "V",
"W": "W",
"X": "X",
"Y": "Y",
"Z": "Z",
"[": "bracketleft",
"\\": "backslash",
"]": "bracketright",
"^": "asciicircum",
"_": "underscore",
"`": "grave",
"a": "a",
"b": "b",
"c": "c",
"d": "d",
"e": "e",
"f": "f",
"g": "g",
"h": "h",
"i": "i",
"j": "j",
"k": "k",
"l": "l",
"m": "m",
"n": "n",
"o": "o",
"p": "p",
"q": "q",
"r": "r",
"s": "zcaron",
"t": "t",
"u": "u",
"v": "v",
"w": "w",
"x": "x",
"y": "y",
"z": "z",
"{": "braceleft",
"|": "bar",
"}": "braceright",
"¡": "exclamdown",
"¢": "cent",
"£": "sterling",
"¤": "currency",
"¥": "yen",
"§": "section",
" ̈": "dieresis",
"«": "guillemotleft",
"": "hyphen",
" ̄": "macron",
" ́": "acute",
"·": "periodcentered",
" ̧": "cedilla",
"»": "guillemotright",
"¿": "questiondown",
"À": "Agrave",
"Á": "Aacute",
"Â": "Acircumflex",
"Ã": "Atilde",
"Ä": "Adieresis",
"Å": "Aring",
"Æ": "AE",
"Ç": "Ccedilla",
"È": "Egrave",
"É": "Eacute",
"Ê": "Ecircumflex",
"Ë": "Edieresis",
"Ì": "Igrave",
"Í": "Iacute",
"Î": "Icircumflex",
"Ï": "Idieresis",
"Ð": "Eth",
"Ñ": "Ntilde",
"Ò": "Ograve",
"Ó": "Oacute",
"Ô": "Ocircumflex",
"Õ": "Otilde",
"Ö": "Odieresis",
"×": ".null",
"Ø": "Oslash",
"Ù": "Ugrave",
"Ú": "Uacute",
"Û": "Ucircumflex",
"Ü": "Udieresis",
"Ý": "Yacute#1",
"Þ": "Thorn",
"ß": "germandbls",
"à": "agrave",
"á": "aacute",
"â": "acircumflex",
"ã": "atilde",
"ä": "adieresis",
"å": "aring",
"æ": "ae",
"ç": "ccedilla",
"è": "egrave",
"é": "eacute",
"ê": "ecircumflex",
"ë": "edieresis",
"ì": "igrave",
"í": "iacute",
"î": "icircumflex",
"ï": "idieresis",
"ð": "Yacute",
"ñ": "ntilde",
"ò": "ograve",
"ó": "oacute",
"ô": "ocircumflex",
"õ": "otilde",
"ö": "odieresis",
"ø": "oslash",
"ù": "ugrave",
"ú": "uacute",
"û": "ucircumflex",
"ü": "udieresis",
"ý": "yacute",
"þ": "thorn",
"ÿ": "ydieresis",
"ı": "dotlessi",
"Ł": "Lslash",
"ł": "lslash",
"Œ": "OE",
"œ": "oe",
"Š": "Scaron",
"š": "scaron",
"Ÿ": "Ydieresis",
"Ž": "Zcaron",
"ʺ": "hungarumlaut",
"ˆ": "circumflex",
"ˇ": "caron",
"ˉ": "macron",
" ̆": "breve",
" ̇": "dotaccent",
" ̊": "ring",
" ̨": "ogonek",
" ̃": "tilde",
"–": "endash",
"—": "emdash",
"‘": "quoteleft",
"‚": "quotesinglbase",
"“": "quotedblleft",
"”": "quotedblright",
"„": "quotedblbase",
"†": "dagger",
"‡": "daggerdbl",
"...": "ellipsis",
"‹": "guilsinglleft",
"›": "guilsinglright",
"−": "minus",
"∙": "periodcentered"
}
},
"cmapTableIndex": [
"Unicode, Unicode 1.0",
"Macintosh, Mac Roman",
"Windows, Windows Unicode BMP"
],
"headTable": {
"unitsPerEm": 1000,
"xMin": -89,
"yMin": -337,
"xMax": 691,
"yMax": 744
},
"hheaTable": {
"ascent": 744,
"descent": -337,
"lineGap": 0
},
"OS2Table": {
"usWeightClass": 400,
"usWidthClass": 5,
"fsType": 2
},
"postTable": {
"isFixedPitch": 0,
"italicAngle": 0.0
},
"layoutMetrics": {
"unitsPerEm": 1000,
"boundingBox": {
"xMin": -89,
"yMin": -337,
"xMax": 691,
"yMax": 744
},
"ascent": 744,
"descent": -337,
"lineGap": 0
},
"summary": {
"fontFamily": "OcrB",
"fontSubfamily": "Regular",
"version": "Altsys Fontographer 3.5 4/15/93",
"weightClass": 400,
"isItalic": false
}
}